You've taken a full English practice test, the score came back as one number, and you still can't answer the only question that matters. Would that result hold on test day?
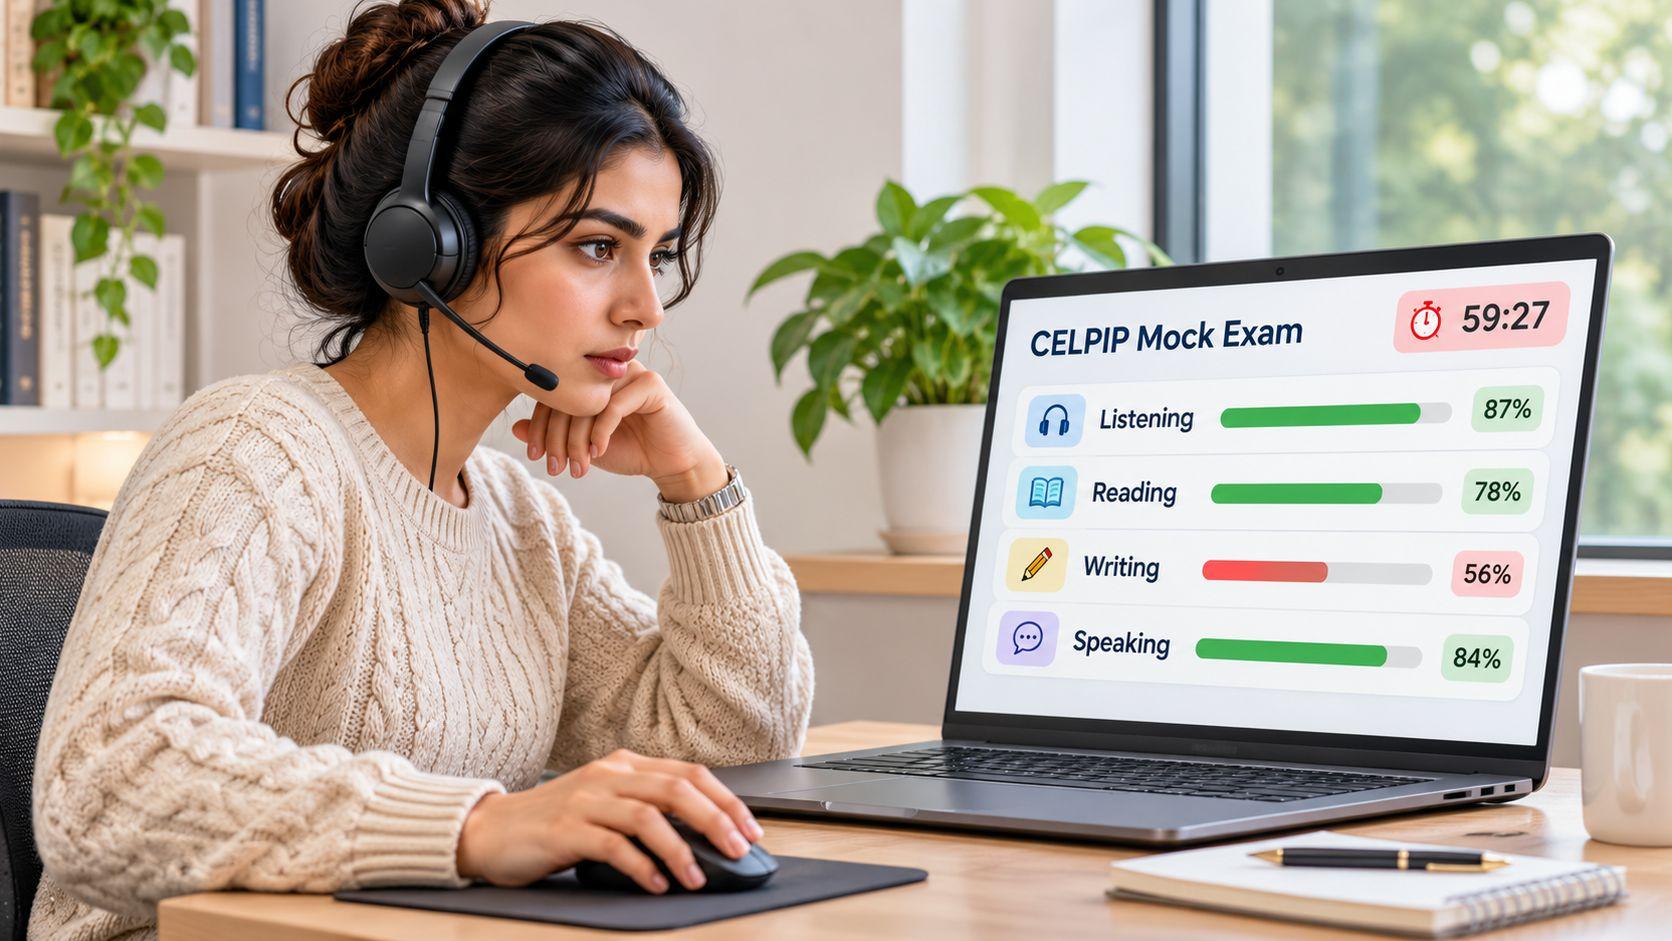
A practice test is a measuring instrument, and it measures something useful only when three conditions hold. Results come back skill by skill, so a strong reading score can't hide a weak speaking score. The clock matches the exam, so you find out what happens to your accuracy when time runs short. And the marking follows the criteria raters apply, not just whether the sentences look tidy. Automated tools can polish your grammar all afternoon and never move the criterion scores that decide your level.
The Four Skills an English Practice Test Covers
Immigration, Refugees and Citizenship Canada accepts CELPIP-General, IELTS General Training and PTE Core for Express Entry, and each accepted test has to measure listening, reading, writing and speaking, as IRCC's accepted language tests page states.
That four-skill requirement exists because of who sits these exams. Candidates take CELPIP because a benchmark level decides whether an immigration application moves, and the level is reported per skill. A practice test that skips one skill, or times it loosely, measures something the exam never asks for.
A quick note on who's talking. Celprep builds CELPIP-style practice and describes itself as an independent practice resource. CELPIP is a registered trademark of Paragon Testing Enterprises; this is not material from the official test provider.
The CELPIP-General structure a practice test should reproduce looks like this.
| Skill | Format | Scored items |
|---|---|---|
| Listening | Conversations, announcements and discussions | 47 questions, about 47 minutes |
| Reading | Correspondence, diagrams and viewpoints | 38 scored points, about 55 minutes |
| Writing Task 1 | Email of 150 to 200 words | 1 response, 27 minutes |
| Writing Task 2 | Survey response of 150 to 200 words | 1 response, 26 minutes |
| Speaking | Advice, experience and prediction tasks | 8 tasks, about 20 minutes |
How to read that table
Start with your own program before the rows. Express Entry needs all five, because every skill feeds a separate benchmark level. The scoring works like four separate doors: one weak component can hold an application even when the other three look strong.
Then rank the rows against your last real attempt and pick the one furthest below target. Three habits keep the table honest. Time every section from the first attempt, so pacing is never a test-day surprise. Record a score per row, never a five-item average, because averaging is exactly what hides a blocking component. Match the format as well as the topic, since a listening set built from announcements and discussions trains something a vocabulary quiz never touches.
Notice what the rows share. The two writing tasks and the speaking set are all production under pressure: fixed word counts, fixed minutes, no second draft. Reading and listening at least let you check your work as you go. That difference is why a single blended score tells you so little, and why tidy sentences in a writing task can still sit under a low task-completion or coherence rating.
Whatever else a study week contains, it should include repeated, timed production in all four skills. Grammar drills feed the skills. Timed rehearsal across the full table is what turns them into a score.
How to Run a Practice Cycle from Diagnosis to Full Mock
Timed, full-format practice does something untimed drills can't. It measures. CELPIP's test format and scoring guidance explains that format-and-timing exposure helps candidates get familiar with question types and test-day conditions, and its official practice materials pair timers with instant Listening and Reading scores plus performance standards for Writing and Speaking.
The mechanism is procedural rather than linguistic. Rehearse under the same preparation and response limits often enough and you stop spending minutes on decisions that should be automatic. You also learn whether your accuracy survives a heavier cognitive load, which is the only version of your ability the exam will ever see.
Three phases, each with one job.

Phase 1, untimed diagnostic. One email, one survey response, one reading set, one listening set, one speaking task. No clock. Write down exactly where each answer breaks down: the sentence you misread, the option you talked yourself into, the request you forgot to state.
Phase 2, section-timed sets. Now apply the official time to each part. One reading set on its 55-minute clock, one writing task on its 27 minutes. The purpose isn't volume. It's making pacing automatic so it stops consuming attention during the exam.
Phase 3, full-length simulation. All sections back to back, no breaks beyond the official ones, in a single sitting. This is the only phase that tells you whether your ability holds when fatigue arrives in the fourth section.
What to log after every simulation
Four entries, every time, in the same place. Accuracy per section. Completion status, meaning whether every item got an answer. Response length on the productive tasks, because an under-length email loses marks before anyone reads a word of the content. Error category for each miss, using the same labels across attempts so trends show up instead of noise.
The log is what turns a score into a decision. Say a candidate scores comfortably on an untimed reading set but leaves the last six items blank at full length. Nothing in the record suggests a comprehension problem, because the blanks cluster at the end. The next action is a section-timed reading set with a per-item budget and a mark-and-move rule, not another hour of untimed reading.
Practical rule: Repeat the full mock only after the section-timed sets show the same error category has dropped.
When your week is short, these study methods fit around the three phases without breaking the cycle.
Scoring Criteria Raters Use for Writing and Speaking
The costly mistake in writing practice isn't a grammar error. It's a clean, correct answer that still lands two levels below target, because the writer repaired every sentence and never touched the thing that lost the marks.
Raters don't score on overall impression. CELPIP's performance standards define separate dimensions for Writing and Speaking, and its raters are trained to apply them consistently. Four dimensions, four different ways to lose points.
| Dimension | What raters check | Usual cause of a low score | Fix to practise |
|---|---|---|---|
| Content and coherence | Ideas are organised and easy to follow | Points listed without links or order | Plan three ideas in order before writing or speaking |
| Vocabulary | Range and precision of word choice | Vague or repeated words | Replace general verbs with precise ones in a second draft |
| Readability or listenability | Grammar, sentence variety, pronunciation and fluency | Short, repetitive sentences or unclear pauses | Combine sentences and record one answer to check pace |
| Task fulfilment | Completeness, relevance, tone and length | Missing request, wrong tone or off-length response | Check the purpose and word count against the prompt before finishing |
Diagnose before you rewrite
When a response scores low, name the dimension that dropped, then revise only that part. It's faster than a full rewrite, and it teaches you which failure you default to under pressure.
Take the long email with clean grammar and no clear request. Readability is fine, vocabulary is fine, the ideas are in order. Task fulfilment is where it died, so the repair is one sentence: restate the request at the end. Now take an email with the request stated three times and no supporting detail. Same score, different cause, and the fix is two concrete details rather than another grammar check.
A low score isn't a verdict on your English. It's a pointer to one of four dimensions, and each one has its own repair.
Track those dimensions separately across attempts instead of averaging them into one headline number. Someone whose task fulfilment climbs while vocabulary stays flat knows precisely what next week is for. Prompts should carry a real communicative purpose and a real length limit too, since both are scored.
Writing and Speaking Templates for Target Bands
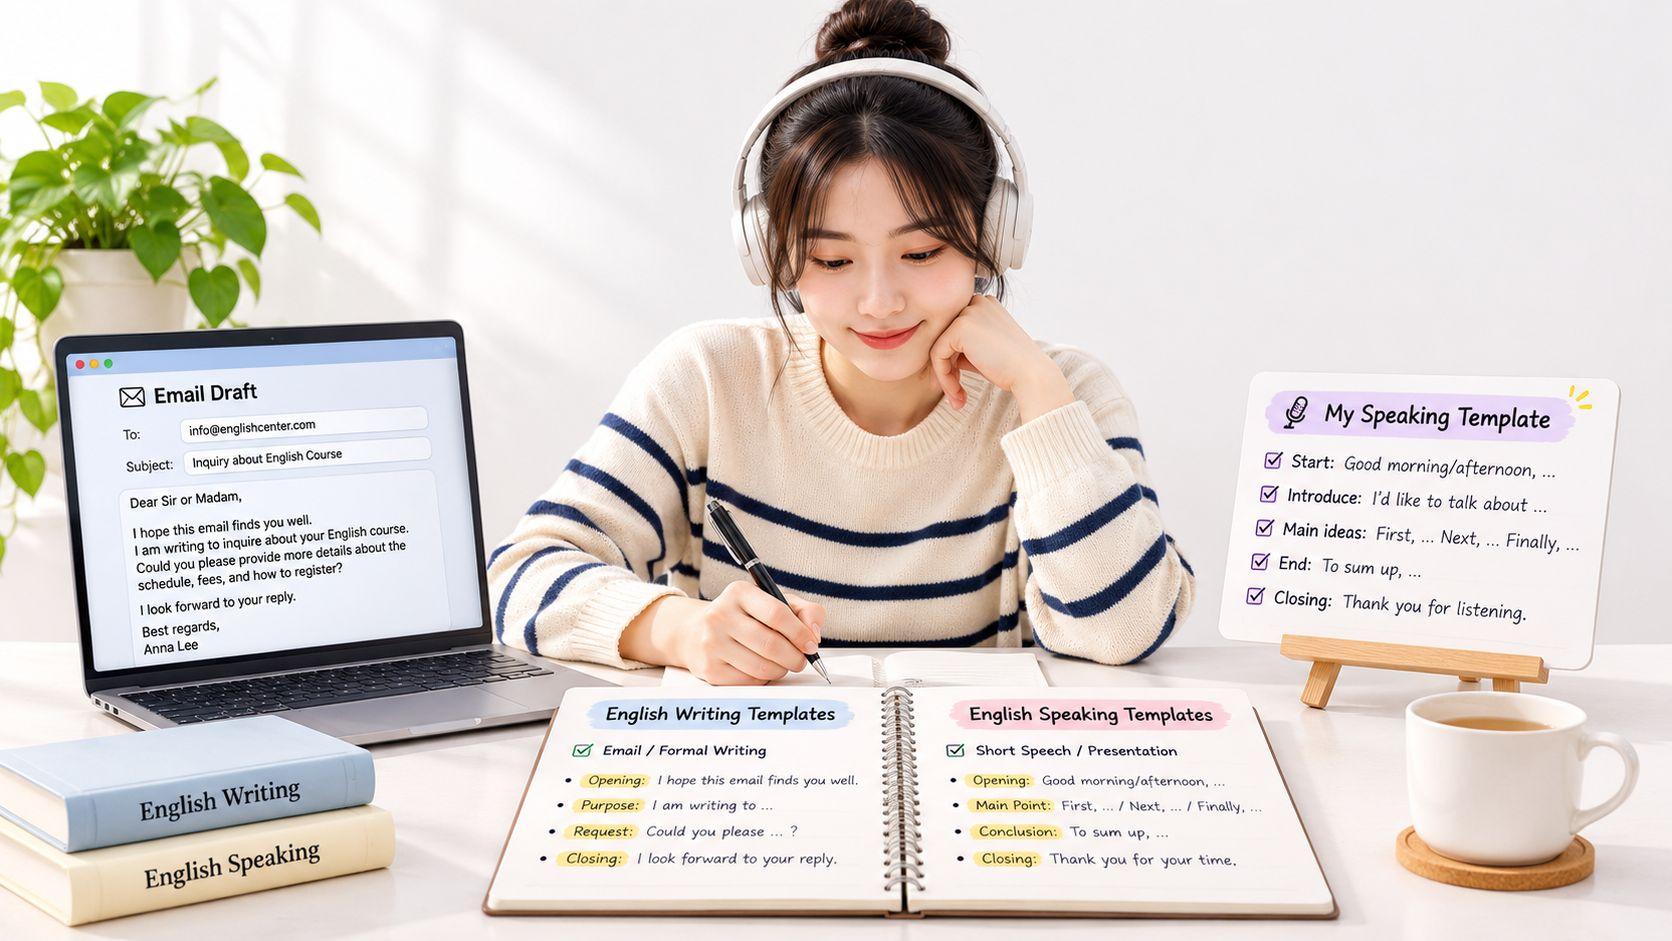
A template isn't a script to memorise. It's a shape that stops you discovering, at minute 20, that you've run out of structure.
Writing Task 1 in four parts
- Greeting and purpose. One line stating why you're writing.
- The problem. A single sentence that summarises it plainly.
- Support. Two or three details a stranger could act on.
- The request. A closing sentence naming exactly what you want and by when.
That's 150 to 200 words in 27 minutes. Spend the final minute on one check: is the request explicit enough that a reader who skims could still answer it?
Writing Task 2, choose and defend
Pick one of the two survey options in your first sentence and don't switch sides. Two reasons, each carrying one concrete example, then a closing sentence that restates the choice in different words. Two developed reasons beat four thin ones, because a half-explained reason reads as an assertion and loses on idea development.
Speaking, three steps and one common slip
Our CELPIP Speaking Task 1 guide works from a three-step shape that fits almost any advice prompt: a greeting with a one-line summary of the problem, then two or three pieces of advice with a reason attached to each, then a conclusion recommending one option.
The mistake that sinks more answers than anything else is giving only one piece of advice. The same guide flags it and hands over the fix, which is mechanical: during preparation time, plan at least two clear suggestions, even if the second is briefer.
Length matters because speaking runs on a clock. The sample answers in that guide stay within 90 to 110 words to fit the 60-second limit, which gives you a realistic target to rehearse against.
Write one template answer per task type this week, then time yourself against it. Finishing at 40 seconds with a single suggestion is useful information. The template just showed you the gap.
Reading and Listening Errors and How to Fix Them
One scoring rule changes how you sit the multiple-choice sections. CELPIP's teacher guidebook confirms that each correct answer earns one point, incorrect answers don't incur a penalty, and responses are scored dichotomously, with blank answers treated as incorrect. An unanswered item and a wrong item cost exactly the same. So answer everything, and stop treating a guess as a risk.
That rule also makes your error log worth keeping, because misses fall into four distinct categories.
| Error type | What it looks like | Fix to practise |
|---|---|---|
| Comprehension error | Choice matches a detail but not the main point | Find the speaker's or writer's purpose before reading options |
| Distractor trap | Choice reuses words from the text but changes the meaning | Underline the claim and eliminate options that only repeat keywords |
| Pacing loss | Items left unanswered when time runs out | Set a per-item time budget and mark, then move on |
| Blank answer | Item left empty at the end of the section | Keep a final sweep to answer every remaining item before time ends |
The fix behind each category
A comprehension error means the choice matched a detail while missing the point, so the repair is to locate the purpose before you read the options at all. A distractor trap borrows the passage's vocabulary and subtly changes the meaning; underline the actual claim and eliminate anything that merely echoes keywords.
Pacing losses look different. The items cluster at the end and the answers stop, which means the clock ran out, not the language. Set a per-item budget, mark the hard ones and move, then return if time allows. Blanks are the cheapest problem in the whole test, solved by a final sweep in the last minute of every section.
Every item deserves an answer. A guess costs nothing; a blank costs a full point.
Say a learner gets half the questions right and leaves nine unanswered. That's a pacing problem wearing a reading problem's clothes, and the next session should be a timed set with a visible budget, not more untimed passages. When you want answer choices broken down one by one, the reading test guide works through them line by line. Sort every miss into one of the four categories after each set.
Using AI Feedback Without Overtrusting It
If instant correction raised scores, everyone with a chatbot would be sitting at Level 10. The evidence points somewhere narrower, and the gap matters most for candidates chasing the top bands.
A recent systematic review of AI-assisted language learning found writing gains strongest in mechanical and organizational areas, while higher-order abilities improve less consistently. Speaking splits the same way: AI helps pronunciation, fluency, anxiety and willingness to communicate, but it doesn't replace human interaction for pragmatic competence and nuanced conversation.
So run one check on every AI-corrected answer: would this response earn the marks against the task, or does it just read more smoothly?
- Rewrite for task fulfilment first. Does the answer do what the prompt asked, in the right tone, at the right length?
- Test clarity on a stranger. If someone who hasn't seen the prompt can't state your main point, the coherence problem is still there.
- Compare against the rubric table. A grammar fix doesn't move task fulfilment, and the tool rarely tells you which dimension it improved.
Unlimited correction has a side effect worth naming. It produces polished answers that sound like everyone else's.
Keep prompts that demand original reasoning and a flexible reply, and treat automated feedback as a first pass over surface accuracy. The AI essay feedback guide goes further into where automated marking helps and where human judgment still decides.
Choose Your Next Practice Step This Week
CELPIP reports results by component, and each one maps to its own benchmark level. CELPIP's guide to CLB scores states that scores from 3 through 12 correspond to the same-numbered Canadian Language Benchmark level, and that Express Entry requires CELPIP-General because it evaluates all four language skills, while the two-skill CELPIP-General LS test isn't accepted for permanent-residence applications. An average can look healthy while one component sits below the line that decides your file.
Fill in your own numbers rather than estimates.
| Component | Next action |
|---|---|
| Listening | Review missed items by error type |
| Reading | Run a timed section set and log blanks |
| Writing | Rewrite one email against the rubric |
| Speaking | Record one answer and check the three-step template |
Then take one action, not five. Pick the component furthest below target, run it through the three-phase cycle, and re-test that component before you touch the others. Readiness means every component clears its own target on a timed attempt, not that one lucky result carried the rest.
The free plan covers enough to begin: one exercise per task type across Writing, Reading, Listening and Speaking, three starter templates, one vocabulary bundle per section, and three submissions a day. Signing up takes 30 seconds and opens the exercises straight away.
Celprep gives you the instrument described here rather than another library of passive lessons: 3,000+ CELPIP-style exercises across all four skills, full mock exams under real test timing, and feedback written against your own response instead of a generic score. Start with the free tier and get a separate result for Listening, Reading, Writing and Speaking before you book anything. Visit Celprep and run your diagnostic this week, so your first score becomes a baseline you can act on.